

TL;DR
Persistent agent memory is information the system can carry into a later session and use when deciding what to do.
The important control point is the write: what gets stored, where it came from, how long it remains valid and what can replace it.
If memory can outlive its source, the system also needs rules for deletion and repair so old or untrusted information does not keep shaping future work.
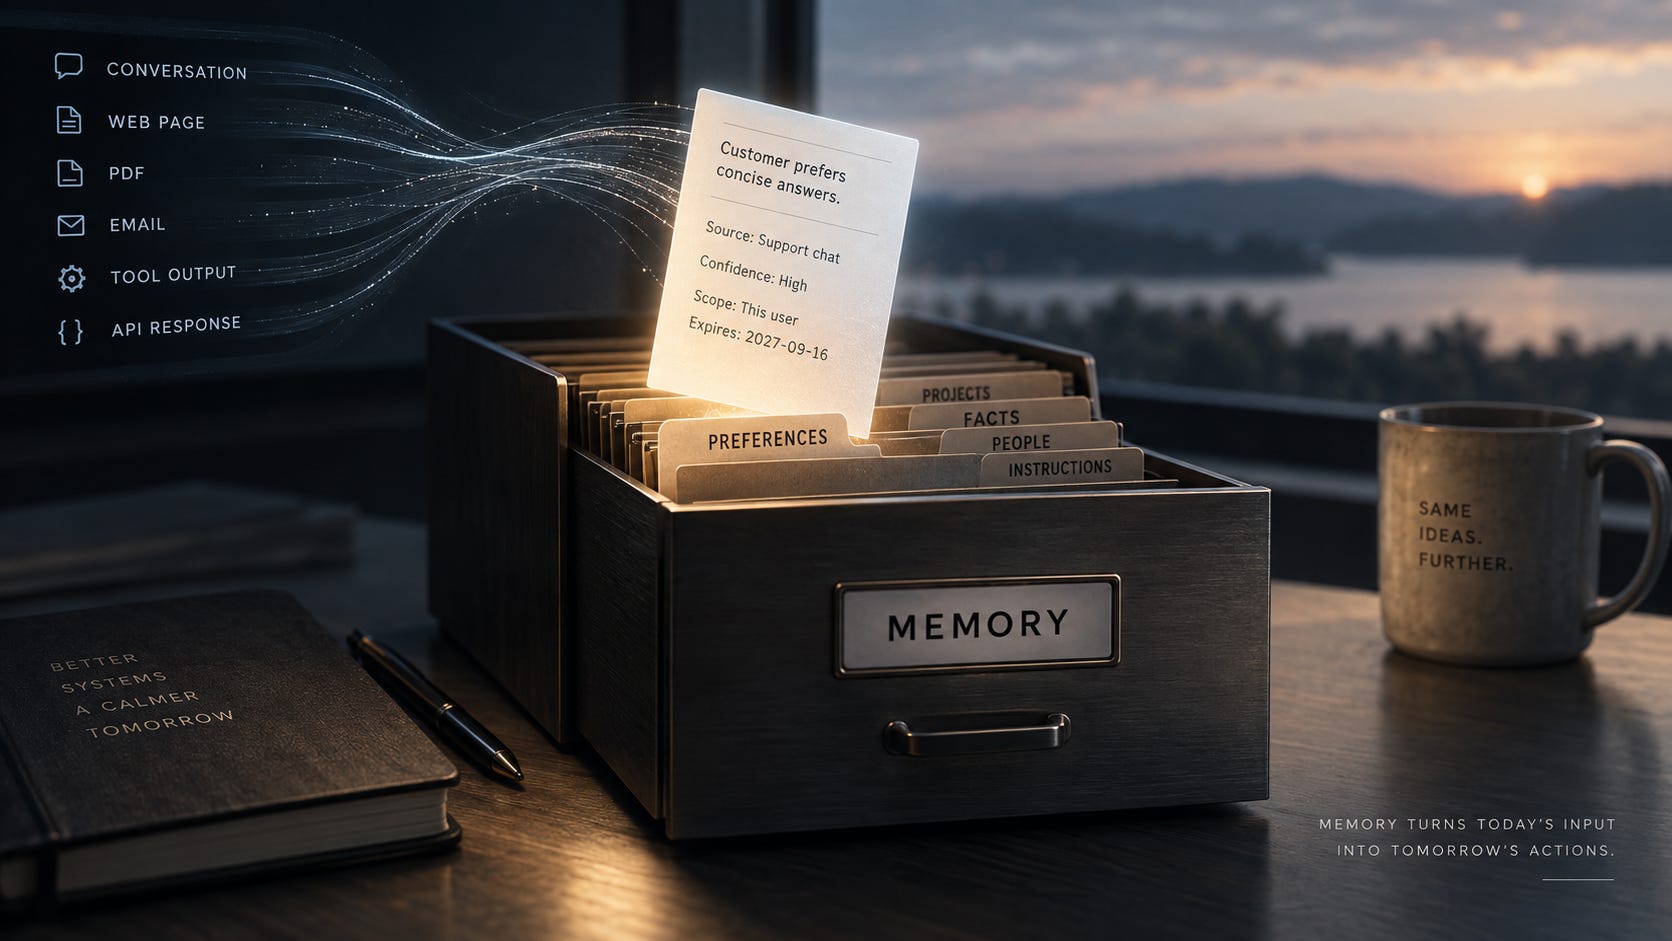
A customer tells an AI agent, “Text me, don’t call.” The agent remembers it.
Three days later, the customer says the opposite. The first conversation is no longer in front of the model. The stored preference is.
Which statement should the agent follow? More important: what tells the system that the old preference is no longer current?
As agents start working across hours, days and multiple sessions, memory stops being a convenience feature. It becomes information the system keeps after the original interaction ends and may use later when deciding what to do.
OpenAI’s new Agents API is one sign of that shift. It supports agents that can keep working for hours and can automatically compress older context as a session approaches its limit. In plain English, the system can replace older conversation detail with a shorter summary so the agent can keep going without carrying every earlier token forward. That helps a long session continue. It doesn’t answer a different question: what should the system remember after that session is over?
That second question is where I think the architecture gets more interesting.
Memory is several different things wearing one label
The Agentic AI Foundation published a useful survey this month because it separates several things that often get collapsed into the word “memory.” Conversation history, compressed summaries, files, searchable document stores, workflow checkpoints, extracted preferences and shared records can all survive beyond a single interaction with the model. They don’t survive for the same reason, and they don’t fail in the same way.
A checkpoint may exist so an unfinished workflow can resume after a crash. A searchable document store may exist so the agent can find source material later. An extracted memory may exist because the system decided a fact or preference should influence future sessions.
That last category is where the write path matters most. By write path, I mean the steps between seeing new information and deciding that the agent should remember it later.
source
  -> interpretation
  -> proposed memory
  -> write decision
  -> stored memory
  -> later retrieval
  -> action
The source might be a user, a document, a tool result or another agent. The proposed memory may be explicit, such as “the customer prefers phone calls,” or it may be an inference the agent made from behavior. Once that conclusion is stored, the original evidence may disappear from the model’s current context while the conclusion remains available.
That changes the trust problem. I wrote in The Control Channel Never Went Away about untrusted data beginning to behave like instructions when an agent can’t keep data and control cleanly separated. Persistent memory stretches that problem across time. A bad instruction doesn’t have to win immediately if it can first become something the system remembers.
Every stored memory becomes a future input
This isn’t only a theoretical problem. Recent memory-security research is beginning to test what happens when bad information gets written into memory and survives long enough to affect a later task.
MemSecBench, a July preprint, evaluated 310 cases across 24 combinations of agent software, memory systems and language models. In that controlled benchmark, malicious memory remained stored in 84.2% of cases and the full chain from writing the bad memory to triggering a later action succeeded in 50.3%. Those numbers don’t tell us how often memory poisoning happens in production. They show that, in the systems the researchers tested, a harmful write could survive long enough to matter later.
MemSentry, published in September, approaches the same problem from the control side. Its proposed framework checks a persistent-memory write before storage and sends it down one of three paths: accept it, send it for review or quarantine it. The framework is a research prototype, but I like where the control sits. The system checks the information before it becomes something the agent can carry into future work.
The security version is easy to see because the input is malicious. The ordinary version may be more common and less dramatic. A user changes a preference. A project decision gets reversed. A policy is replaced. An agent infers something that was never actually stated. A summary turns ten pages of evidence into one wrong sentence.
All of those can create the same failure: yesterday’s conclusion remains available after the facts underneath it have changed.
A timestamp doesn’t solve that by itself. Newer information isn’t automatically more authoritative. A casual comment from this morning shouldn’t overwrite an approved policy from last week merely because it’s newer. The system needs to know what kind of information it stored, where it came from and why it was allowed to matter.
The write needs a record of its own
I wouldn’t let a durable memory be only a sentence plus the numerical fingerprint a search system uses to find similar text.
At minimum, I want enough information attached to the memory to answer a few basic questions: where did it come from, who or what wrote it, what does it apply to, when was it observed, was it stated or inferred and has something newer replaced it?
An illustrative record could look like this:
value: "prefers phone calls"
source: user_statement
observed_at: 2026-09-16T14:12:00Z
scope: customer_123
status: current
supersedes: memory_481
The field names aren’t the point. The relationships are.
Without a source, you can’t tell an approved instruction from something the agent guessed. Without scope, meaning where the memory is allowed to apply, a preference from one customer or project can leak into another. Without a record of what it replaces, both “text me” and “call me” can remain available at the same time. Without a current status, the system may retrieve an old fact simply because it still looks relevant.
This is why the write path deserves its own policy. Retrieval controls what the agent can find later. A write policy controls what information the system is allowed to preserve for that later use.
Deleting the source may not delete the memory
Deletion gets harder once the system has created new information from the original source.
Suppose a user deletes the conversation where a preference first appeared. The same information may still exist in an extracted profile, a summary, a searchable index, a database that links people and facts, a cache or a shared memory another agent can read. Removing the original message doesn’t necessarily remove the copies or conclusions the system created from it.
The Agentic AI Foundation survey calls out this problem directly. A durable-memory system needs a way to delete information that was derived from a source, not only a delete button for the source itself.
Repair matters for the same reason. MemSecBench found that, after a successful memory-poisoning case, selective repair worked in 56.1% of the cases the researchers tested. That’s a benchmark result, not a production failure rate. But it raises a useful design question: can you remove one bad memory without deleting everything useful the agent learned afterward?
I made a similar argument in Recovery-First Automation: Undo Is the Feature. Automation gets safer when reversal is designed in before the bad action happens. Persistent memory needs the same discipline. If the only recovery option is “wipe the agent and start over,” the system can remember, but it can’t repair what it remembers.
Audit one thing your agent remembers
Pick one fact or preference your agent can carry into a future session and follow it from the original source to the later action.
Who wrote it? What source justified it? Was it explicitly stated or inferred? Where is it allowed to apply? What can replace it? When should it expire? If the source is deleted, where else does the information survive? If it’s wrong, can you remove that one memory without resetting everything else?
If those questions don’t have answers, start at the write path. That’s where the system decides what information tomorrow’s agent will still be allowed to use.
P.S. Personally, I decided to run the experiment on my own AI memory.
I started with Airtable as the place where long-term memories are stored, with the model’s built-in memory still handling the faster conversational layer and Dropbox holding the supporting evidence, backups and recovery material.
The interesting part wasn’t storing the memories. That was easy. The useful work was making every memory carry enough context to explain where it came from, where it applies, how much authority it should have, whether it is still current and what has changed since it was first stored. That keeps something said from quietly becoming “true” forever just because the system remembered it once.
I also kept the stored memory separate from the evidence that justified it. Instead of erasing old information when something changed, I kept a history of those changes and linked a new memory to the older one it replaced. Even in a small personal system, that made it much easier to see why something was remembered, what replaced it and how to repair it if it was wrong.
Postgres was the obvious comparison as the experiment got larger. But the first lesson has already been simpler than that: the database matters less than the rules around what gets remembered, why it is trusted, when it should change and how it can be corrected.
Resources
OpenAI, “Introducing the Agents API,” September 10, 2026: https://openai.com/index/introducing-the-agents-api/
Agentic AI Foundation, “Agent memory: patterns, tradeoffs, open problems,” September 8, 2026: https://aaif.io/blog/agent-memory-patterns-tradeoffs-open-problems
Xuanze Chen et al., “MemSecBench: Tracking Agent Memory Poisoning from Persistence to Consequence and Repair,” arXiv:2607.27080, July 29, 2026: https://arxiv.org/abs/2607.27080
Ayan Roy and Kaustuvi Basu, “MemSentry: A Framework for Detecting Persistent Memory Poisoning in Agentic AI,” arXiv:2609.08747, September 8, 2026: https://arxiv.org/abs/2609.08747